ChatGPT Enterprise Training Singapore
1-day onsite ChatGPT Enterprise training. Build shared custom GPTs on your own files, analyze spreadsheets, and establish verification standards for work.
Everyone has ChatGPT. Almost nobody has built anything with it.
We train your team onsite, on your own files and data, to move past asking questions — building shared custom GPTs, analysing real spreadsheets, and standardising the work so it survives the person who made it.
Runs inside your organisation’s ChatGPT Enterprise workspace, under your existing admin controls. Enterprise NDA.
This is not a prompting webinar. Your team builds things that other people then use.
Individual familiarity with ChatGPT is already universal and worth very little. The gap is between forty people each improvising in their own chat window and a team with shared, reviewed assistants that produce the same quality whoever runs them.
Generic AI Training
- Prompt lists. A deck of clever prompts that nobody opens again after the session ends.
- Chat-only habits. Never reaches custom GPTs, file analysis or the connectors where the real leverage sits.
- Sample data. Tidy demo files that behave nothing like your actual exports and documents.
- No standard. Everyone leaves with a personal trick and the organisation learns nothing.
Specialised Enterprise Training
- Shared custom GPTs. Built during the session on your own material, then published to the people who need them.
- Practitioner led. Taught by someone who has delivered enterprise systems in regulated environments, not a prompt influencer.
- Your workspace. Your own ChatGPT Enterprise tenant, your files, your admin and retention settings.
- Verification built in. Every workflow includes how output gets checked before anyone relies on it.
Six workflows, built by your team, during the day.
Roughly 30% instruction, 70% hands-on. Everyone works in your own workspace, on work they actually own.
- Custom GPTs
- Spreadsheet Analysis
- Long Document Review
- Research & Synthesis
- Drafting Standards
- Output Verification
What changes the next morning
Specific tasks, not general capability.
- Before: Forty people improvising forty different prompts for the same task After: One shared custom GPT everyone opens, producing consistent output
- Before: Spreadsheet analysis waiting on the one person who knows the formulas After: Described in plain language, generated, then checked against a known result
- Before: Long reports and contracts read end to end before anyone can act After: Key points extracted with the source cited, then read closely where it matters
- Before: Research that means twenty browser tabs and a lost afternoon After: Structured synthesis with sources listed, ready to verify
- Before: Output trusted because it reads well After: Checked against source as a standing step before it goes anywhere
One day. Your office. Hour by hour.
Short teaching blocks, then your team builds in your own workspace.
- 9:00 What it does well, and where it lies. The failure modes that matter in an enterprise: confident wrong answers, stale knowledge, and the tasks where it should not be used at all. Short and practical.
- 10:00 Working with your own files. Upload real documents and exports. Extract, compare and summarise with the source cited, so a reviewer can check rather than trust.
- 11:30 Spreadsheet and data analysis. Describe the analysis in plain language, generate it, and — the part most training skips — verify it against a result you already know.
- 1:30 Build a custom GPT. The core of the day. Each group builds a GPT for a task their team repeats weekly, with its own instructions and reference files, then tests it against real cases.
- 3:00 Publish, review and govern. Who can see it, how it gets reviewed before sharing, and how you stop forty near-identical GPTs appearing by Christmas.
- 4:00 Demonstrate to the room. Each group shows what they built and hands it to someone who was not involved, to see whether it survives contact with a colleague.
- 5:00 Take it back to work. GPTs published, prompt library exported, owners assigned, and agreement on what the team standardises on next week.
What your team leaves with
Artefacts, not attendance.
- At least one published custom GPT. Built on your own material during the session, tested by someone who did not build it, and available to the team on Monday.
- A reusable prompt library. Documented and exported, so it transfers to people who were not in the room.
- A verification habit. An agreed way of checking generated analysis and claims before they inform a decision.
- A house drafting standard. So documents from different people read like they came from one organisation.
- A governance line. Who reviews a GPT before it is shared, and what is not allowed near the tool at all.
- A short adoption plan. What the team standardises on in week one, and what is deliberately parked.
Who this training is for.
A poor fit wastes a full day on both sides, so we would rather establish that on the call than on the day.
A good fit
- Teams already licensed for ChatGPT Enterprise, Team or Edu
- Six or more people who can be released for a full day
- Willingness to work on your own documents and data
- A leader who can decide what the team standardises on afterwards
Not a fit
- Not yet licensed — free ChatGPT accounts have different data handling and we will not train on them
- Looking for an awareness webinar rather than hands-on work
- Expecting us to integrate ChatGPT with your internal systems; this is training, not implementation
- Unable to release the team for an uninterrupted day
What a ChatGPT session looks like, team by team
One exercise from each team's day, as it runs on your own material in ChatGPT Enterprise.
Finance & Accounting: A variance commentary custom GPT
- What goes in
- A budget-versus-actual export and last quarter's approved commentary, loaded into a custom GPT.
- What is asked
- Draft commentary for every line over the materiality threshold in house style, stating a driver only where the data shows one.
- What comes out
- Draft commentary with each unexplained variance marked "driver to be confirmed by owner".
- What the reviewer checks
- The GPT is tested against a quarter it has not seen; any driver it states that the data does not show fails the test.
HR & People: A policy-answering GPT on your handbook
- What goes in
- Your approved employee handbook and leave policy.
- What is asked
- Build a GPT that answers staff policy questions, quotes the section it relied on and declines when the handbook is silent.
- What comes out
- A shareable GPT plus a ten-question test set.
- What the reviewer checks
- Three of the ten test questions are deliberately outside the handbook; the GPT passes only if it declines all three.
Sales & Marketing: An account brief that separates fact from guess
- What goes in
- A prospect's published annual report and your CRM notes export.
- What is asked
- Produce an account brief with two columns: what the sources say, and what we are inferring.
- What comes out
- A brief the account team can challenge line by line.
- What the reviewer checks
- Every item in the "sources say" column carries a page or note reference; anything without one moves to the inference column.
Customer Service & Support: A reply GPT on your knowledge base
- What goes in
- Your approved knowledge articles and twenty anonymised past tickets.
- What is asked
- Build a GPT that drafts replies in your tone, names the article used and routes anything uncovered to escalation.
- What comes out
- A shared GPT the team uses on live tickets.
- What the reviewer checks
- The twenty past tickets are replayed; drafts are compared with what an experienced agent actually sent.
Operations & Supply Chain: Late-delivery analysis from a CSV
- What goes in
- Six months of purchase order and goods receipt data as a CSV.
- What is asked
- Show late deliveries by supplier and by month, and list the ten worst orders with the days late.
- What comes out
- A summary table and chart for the supplier review.
- What the reviewer checks
- The totals are re-run in a pivot table you control before the figures go to a supplier meeting.
Leadership & Strategy: Scoring candidate use cases
- What goes in
- Short descriptions of eight processes your teams have proposed for AI.
- What is asked
- Score each one for value, effort, data readiness and review burden, and say which scores rest on assumptions.
- What comes out
- A ranked shortlist with the assumptions listed.
- What the reviewer checks
- The leadership team overrides the scores where they know better; the point of the exercise is the conversation, not the ranking.
What your team will have built by 5pm.
The session is built around one commitment: your team publishes at least one working custom GPT, built on your own material and tested by a colleague who did not build it. We scope the day with you beforehand so that outcome is realistic for your team.
Not taught by an AI generalist
Your team will know within twenty minutes whether the trainer has done real work. This is who runs the session.
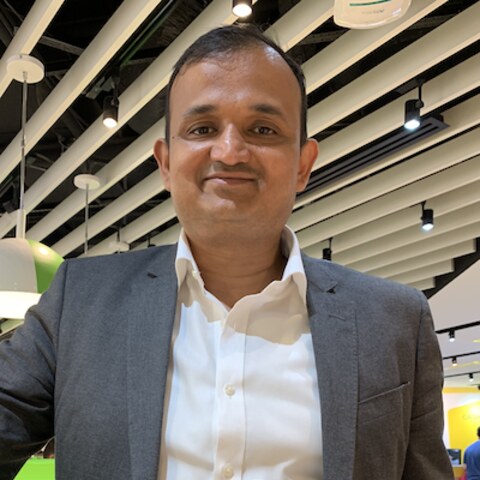
Abhijit Ghosh
Founder, Eagentix · Data & Generative AI Practitioner · Singapore
Sessions are delivered by Abhijit Ghosh, who has spent 25 years in data and AI, including roles at Accenture, IBM, Deloitte, Cloudera, Tibco and Wipro. Sessions are run by the practitioner, not handed to a junior facilitator.
We deliver these sessions under enterprise NDA, and client names are withheld — the same confidentiality that will cover your own session. If you would like a reference conversation, we will arrange one directly with a past client rather than publish a quote.
One day. Your office. Hour by hour.
- 9:00 — What it does well, and where it lies: The failure modes that matter in an enterprise: confident wrong answers, stale knowledge, and the tasks where it should not be used at all. Short and practical.
- 10:00 — Working with your own files: Upload real documents and exports. Extract, compare and summarise with the source cited, so a reviewer can check rather than trust.
- 11:30 — Spreadsheet and data analysis: Describe the analysis in plain language, generate it, and — the part most training skips — verify it against a result you already know.
- 1:30 — Build a custom GPT: The core of the day. Each group builds a GPT for a task their team repeats weekly, with its own instructions and reference files, then tests it against real cases.
- 3:00 — Publish, review and govern: Who can see it, how it gets reviewed before sharing, and how you stop forty near-identical GPTs appearing by Christmas.
- 4:00 — Demonstrate to the room: Each group shows what they built and hands it to someone who was not involved, to see whether it survives contact with a colleague.
- 5:00 — Take it back to work: GPTs published, prompt library exported, owners assigned, and agreement on what the team standardises on next week.
Frequently Asked Questions
Is our data safe during onsite training?
We sign enterprise NDAs prior to the session, and all hands-on exercises run inside your own ChatGPT Enterprise workspace under the admin, retention and access settings your administrators have configured. OpenAI states that business data submitted through its enterprise offerings is not used to train its models by default. We work within whatever configuration you already have rather than changing it.
What exactly will our team have at the end of the day?
At least one published custom GPT built on your own material and tested by a colleague who did not build it, plus an exported prompt library and an agreed verification step. We agree the specific use case with you before the session so it is realistic for your team and their data.
We already use Copilot. Is this redundant?
Not usually. Most organisations end up with more than one tool, and the useful skill is knowing which work belongs where. Copilot sits inside Office and your tenant data; ChatGPT is stronger for open-ended analysis, research and building shared custom assistants. We will say plainly which of your tasks belong in which.
Do we need technical people in the room?
No. Custom GPTs are built through configuration and instructions, not code. Having a workspace administrator available for the first hour helps if permissions or sharing settings need checking, but they do not need to stay.
How do we stop ending up with fifty near-identical GPTs?
That is a real failure mode and we spend a block of the afternoon on it: who reviews a GPT before it is shared, how they are named and owned, and when to improve an existing one rather than build another. Governance is part of the training, not a follow-up conversation.
Do you deliver outside Singapore?
Yes. We deliver onsite across Singapore and the wider Southeast Asia region, and travel further for larger engagements. Remote delivery is possible but hands-on coaching is noticeably better in the room.